AmirHossein (Amir) Razlighi

I am a PhD student at the GrUVi Lab at Simon Fraser University and the University of Cyprus, advised by Ali Mahdavi-Amiri, Daniel Cohen-Or and Yiorgos Chrysanthou.

I work on image and video generation and editing, with a focus on control, and on using video models as world models and reasoners. I also work on 3D/4D scene representations.

flow_matching.demo → ARt = 0.00
noisedata
Each dot is a Gaussian moving along xt = (1−t)ε + t·x1.

About

Portrait of AmirHossein Razlighi

I am a PhD student working on image and video generation and editing. I want diffusion and flow models to be controllable, and I want to understand what video models know about the world, so they can be used as world models and for reasoning.

My recent work is on joint audio-video diffusion models. Soundwich splits the generated audio into stems (speech, music, effects, ambience) that can be edited independently. Sound Sparks Motion edits motion at test time, without retraining the model.

Earlier I worked on 3D and 4D reconstruction at ETH Zurich and INSAIT, and on robot manipulation at the University of Toronto. I did my BSc at Sharif University of Technology, and worked at Tapsi on ETA and navigation models.

Elsewhere: GitHub · Scholar · LinkedIn · X · Medium
News

Research

Control in image and video generation and editing

Precise control over image, video and audio-video diffusion models without retraining them: tuning the conditioning at test time, and splitting what a model generates into parts that can be edited separately.

Soundwich · Sound Sparks Motion

Video models as world models and reasoners

Video diffusion models appear to learn physics, geometry and cause and effect. I want to understand how to use them as simulators of the world, and as models that can reason.

Ongoing

3D and 4D scene representations

Dynamic scene representations: Gaussian Splatting and implicit fields that handle large topological change, and compression that keeps visual fidelity.

N4DE · Confident Splatting · mlx3D

Publications

* equal contribution

2026
Soundwich teaser
arXiv preprint, 2026

Soundwich: Video Generation with Layered and Controllable Audio

Zhuo Ning, AmirHossein Naghi Razlighi, Sagi Polaczek, Daniel Cohen-Or, Ali Mahdavi-Amiri

Decomposes the audio of joint audio-video generative models into independently controllable stems (speech, music, sound effects and ambience) tied together by a shared scene representation. Each stem can be adjusted, muted, replaced or remixed while staying in sync with the video.

arXiv preprint · under review at ICLR 2027

Sound Sparks Motion: Audio and Text Tuning for Video Editing

AmirHossein Naghi Razlighi, Aryan Mikaeili, Ali Mahdavi-Amiri, Daniel Cohen-Or, Yiorgos Chrysanthou

A test-time tuning framework for motion-focused video editing inside audio-visual generative models. Instead of retraining, we tune two lightweight variables, an audio latent and a text-conditioning residual, guided by vision-language model feedback. The learned controls transfer across videos.

2025
Confident Splatting teaser
Preprint, 2025

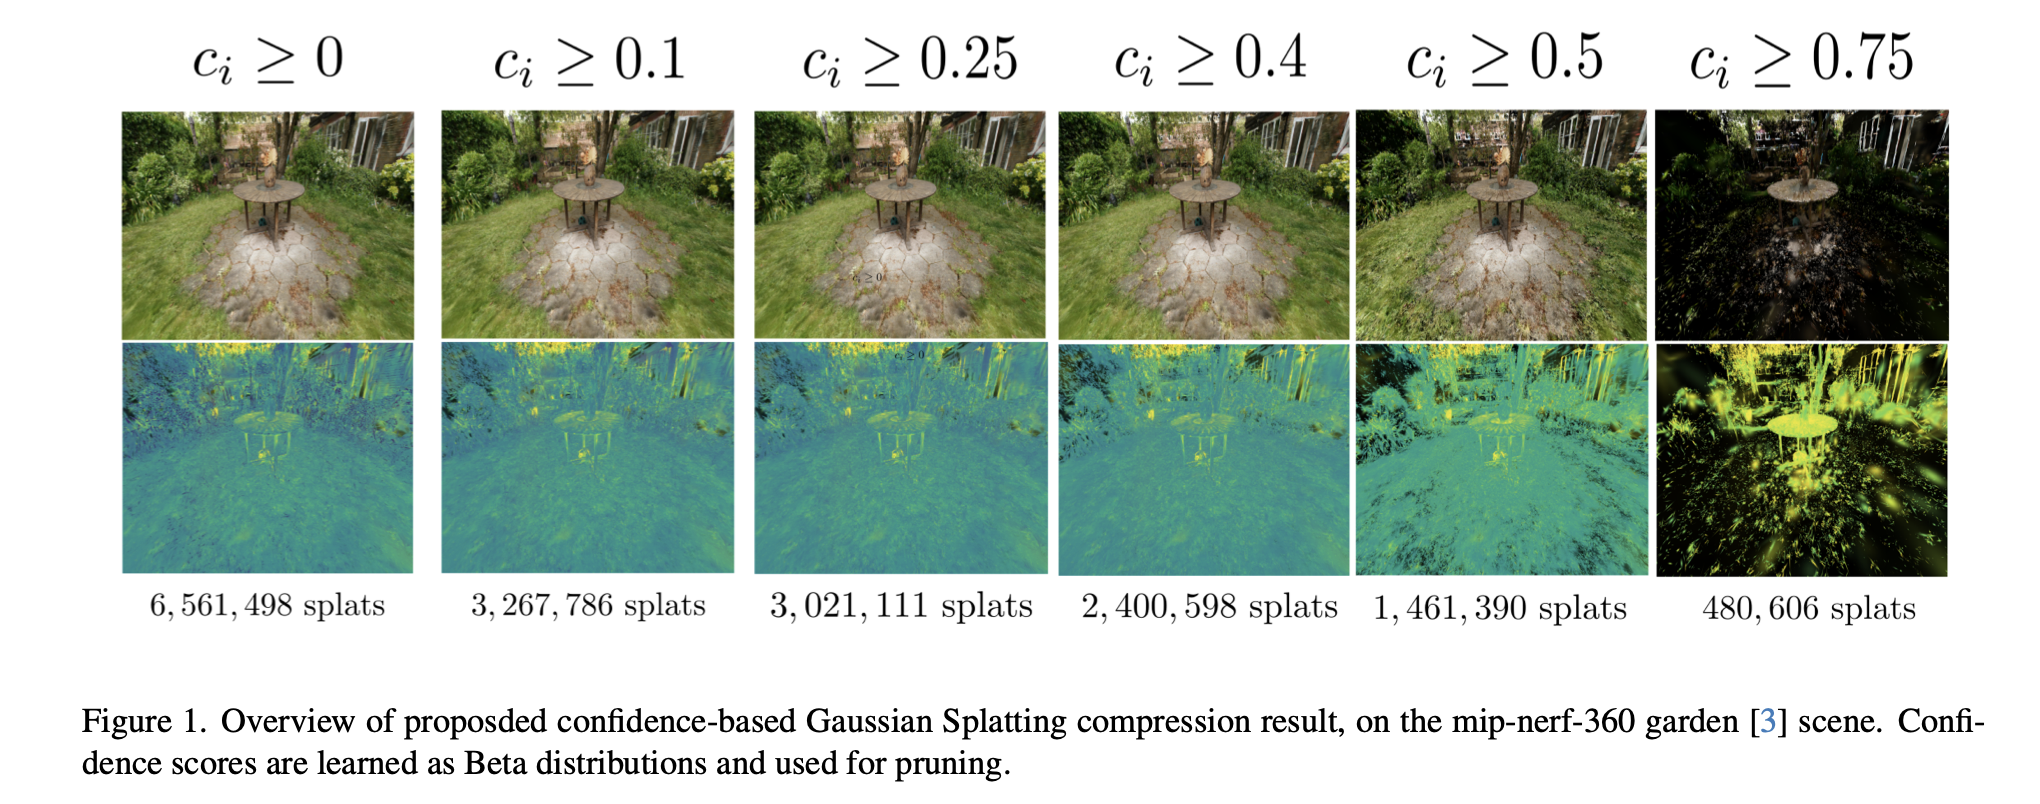
Confident Splatting: Confidence-Based Compression of 3D Gaussian Splatting via Learnable Beta Distributions

AmirHossein Naghi Razlighi, Elaheh Badali Golezani, Shohreh Kasaei

Lossy 3DGS compression with learnable Beta-distribution confidence scores. Low-confidence splats are pruned while visual fidelity is preserved. The method is architecture-agnostic and introduces average confidence as a scene-quality metric.

2024 AND EARLIER
N4DE teaser
Preprint, 2024

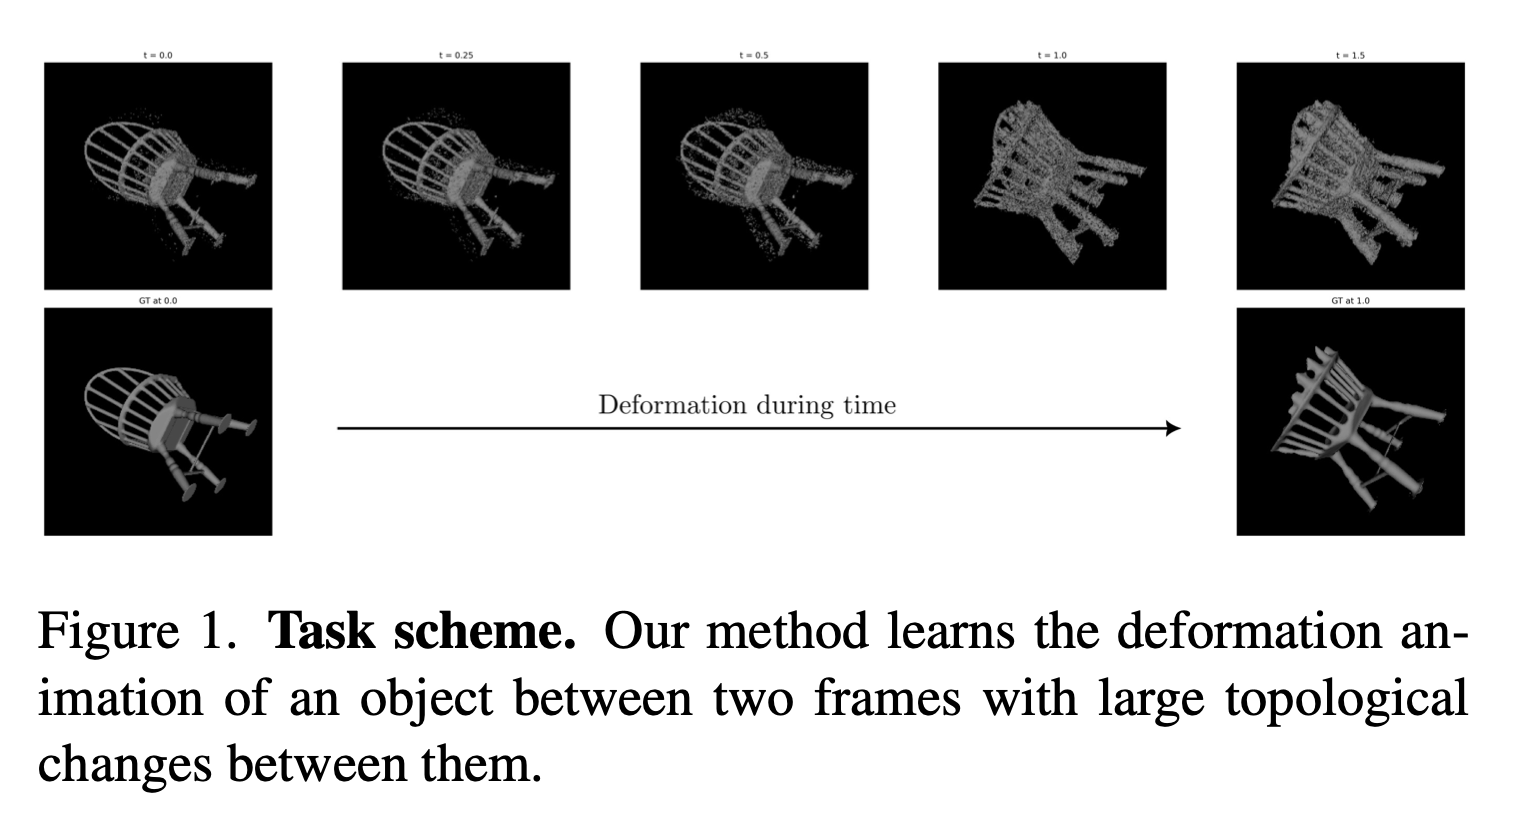
N4DE: Neural 4D Evolution under Large Topological Changes from 2D Images

AmirHossein Naghi Razlighi, Tiago Novello, Asen Nachkov, Thomas Probst, Danda Paudel

A new architecture and temporal-consistency technique for 4D reconstruction under large topological changes, with a Gaussian Splatting rendering scheme and a geometry-appearance disentanglement learned directly from RGB images.

MARS teaser
Preprint, 2023

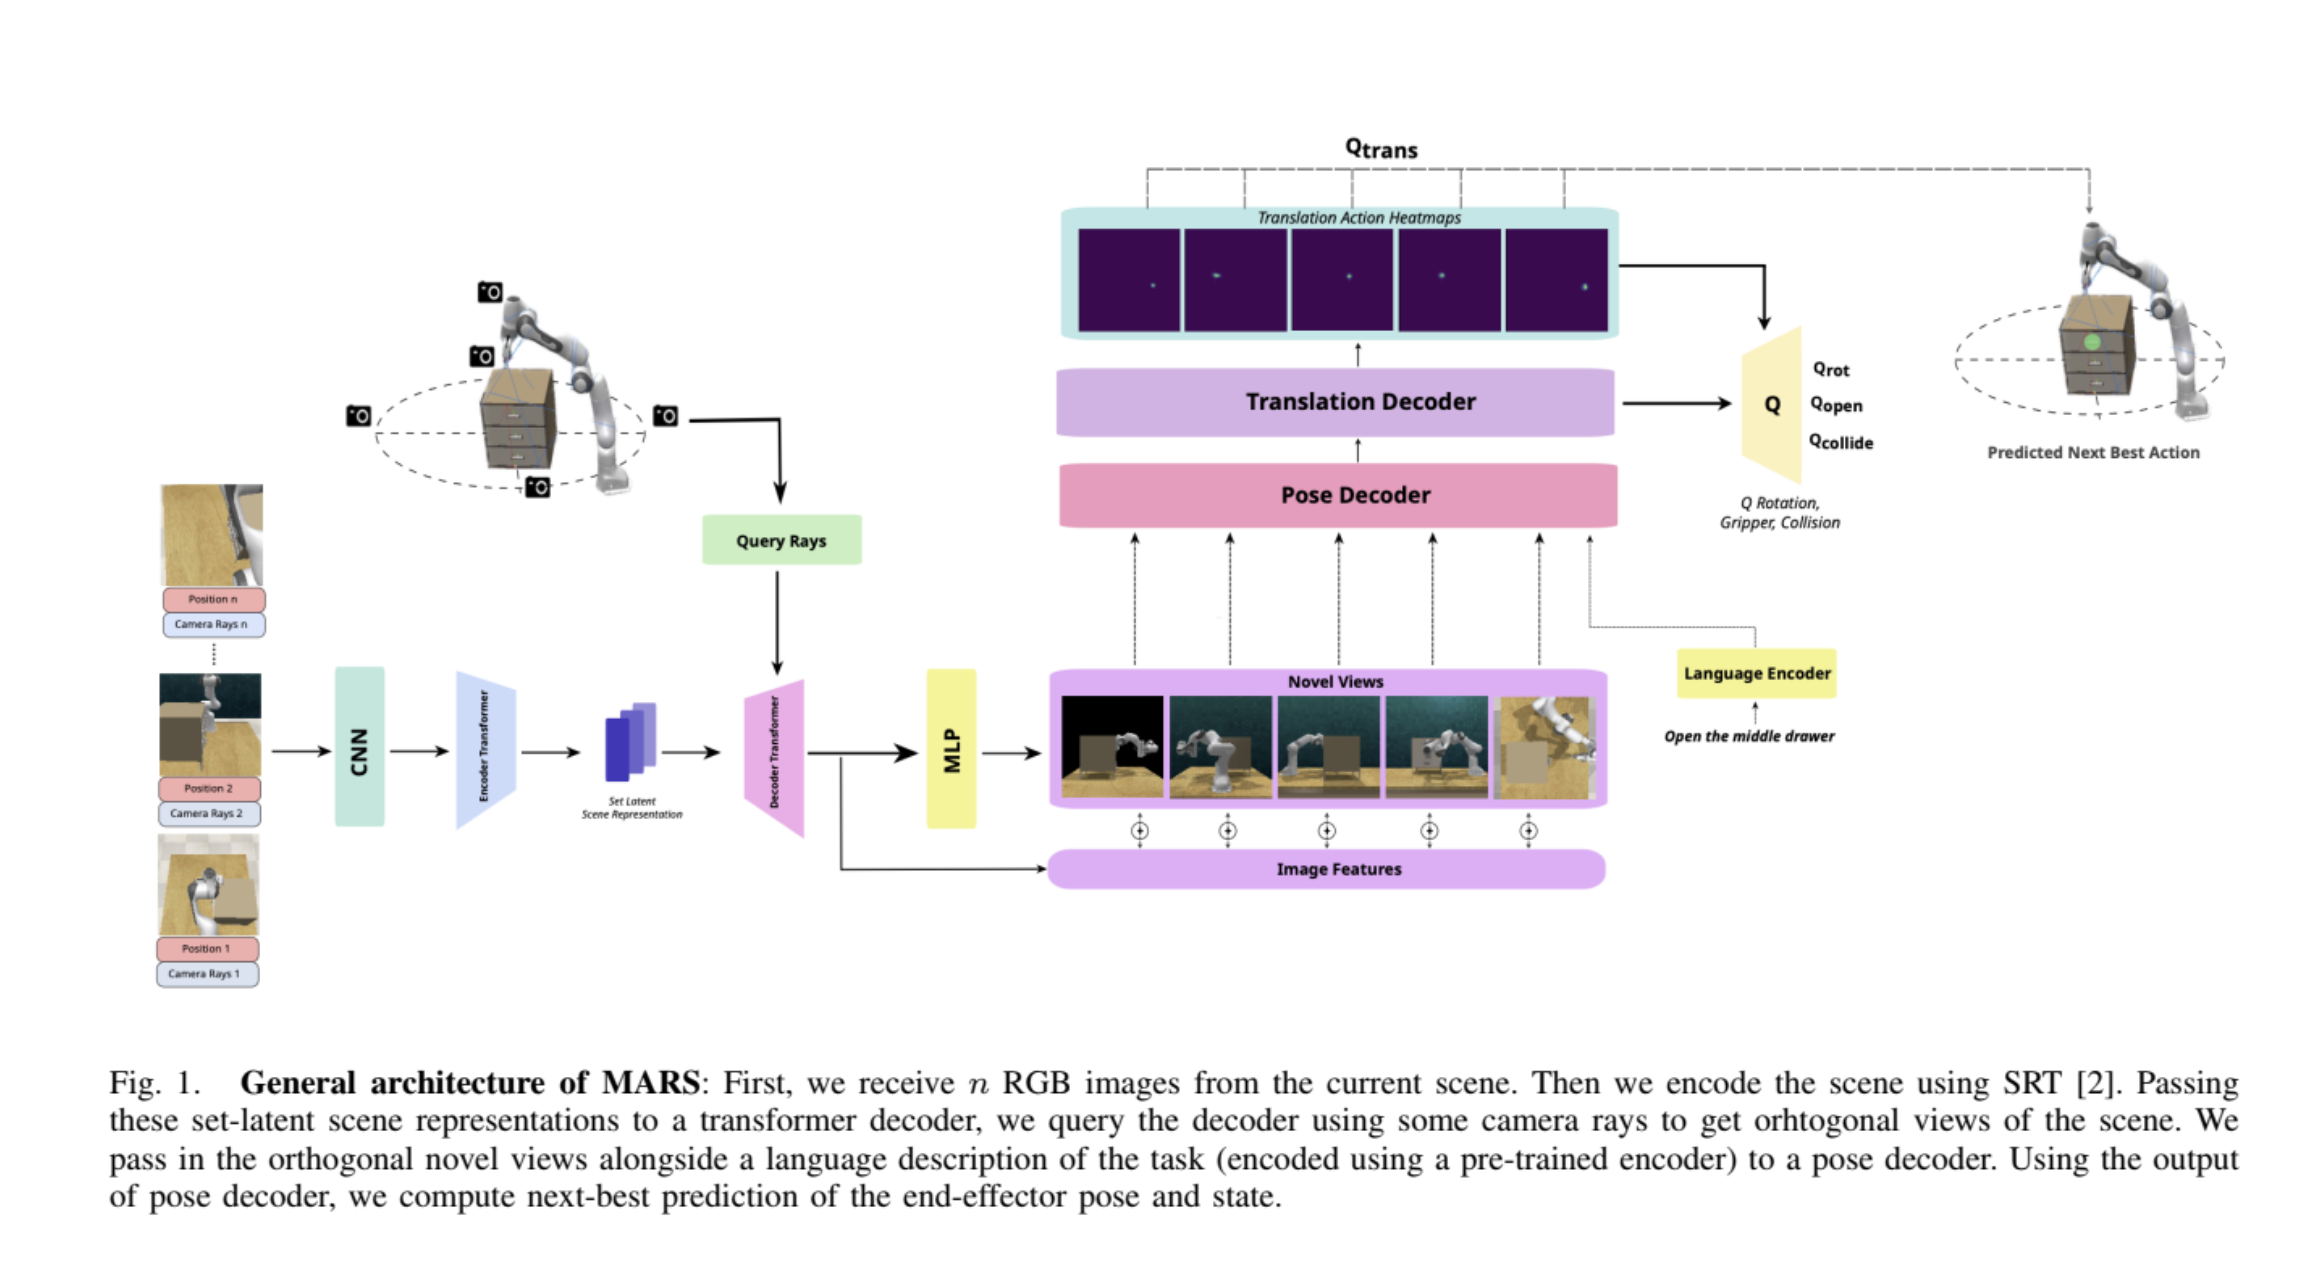
MARS: Multi-task Action Prediction for Robot Manipulation based on Scene Representation

Haoping Xu, Richard Hanxu*, AmirHossein Naghi Razlighi*, Alan Aspuru-Guzik, Florian Shkurti, Animesh Garg

Uses Scene Representation Transformers to render novel views from RGB observations, then predicts end-effector poses and gripper states from language-conditioned keyframe demonstrations.

Open source

Mostly tools for 3D vision and generative models on Apple Silicon.

✦

Selected for Anthropic's Claude for Open Source program. My main open-source projects are mlx3D and mlx_diffuser.

Experience

Research

  • Jan 2026 – presentGrUVi Lab, Simon Fraser UniversityPhD student, research assistant

    Video generative models and 3D computer vision, with Ali Mahdavi-Amiri and Daniel Cohen-Or.

  • Jul 2026 – presentCYENS Centre of Excellence, CyprusResearch Scientist (part-time)

    Machine learning and computer graphics research.

  • Jun – Oct 2024INSAITSummer research intern

    Dynamic 3D reconstruction with SDFs inside Gaussian Splatting; built a dataset of hard deformable scenes.

  • Jun 2023 – Jul 2024ETH ZurichResearch assistant, with Danda Paudel

    NeRFs for dynamic scenes; SDF morphing from RGB images and SDF-based regularizers.

  • 2023University of TorontoSummer research intern, with Florian Shkurti and Animesh Garg

    Robot manipulation from NeRF-based scene encodings.

Industry

  • Mar 2025 – Jan 2026TapsiData Scientist, promoted to Senior Expert Data Scientist (Jul 2025)

    Led two projects from research to production on the MAP team: a GNN for spatio-temporal city modelling and ETA prediction, and an attention-based ETA post-processing model.

  • Feb – Sep 2022Tapsi LabJunior AR Systems Engineer (co-op)

    First member of Tapsi Lab R&D. Built the Driver-Arrived AR feature, running the full pipeline client-side with TensorFlow.js.

Education

  • Jan 2026 – presentUniversity of CyprusPhD, Computer Science
  • 2020 – 2025Sharif University of TechnologyBSc, Computer Engineering · GPA 19.27 / 20, ranked 13th of 194

Honors

Earlier projects

Implementations from scratch, mostly for learning.

Tiny NeRF

A tiny NeRF in PyTorch, small enough to train on a CPU.

GitHub
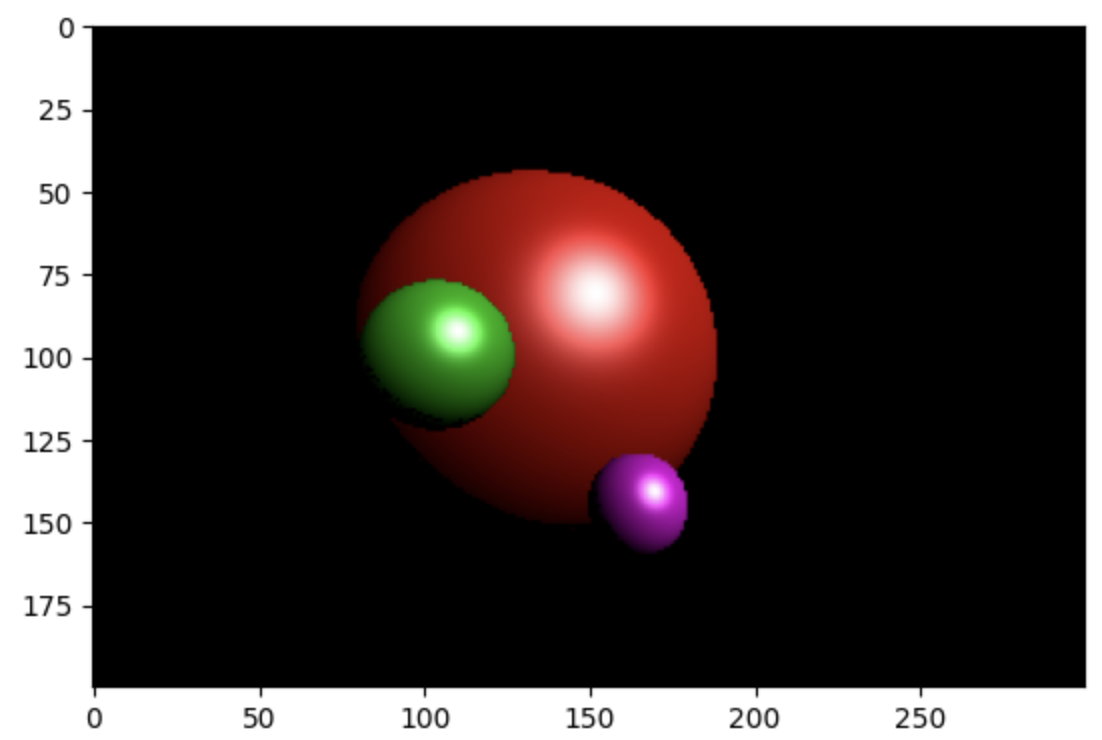
Ray tracing from scratch

Basic ray tracing with only NumPy and Matplotlib.

GitHub
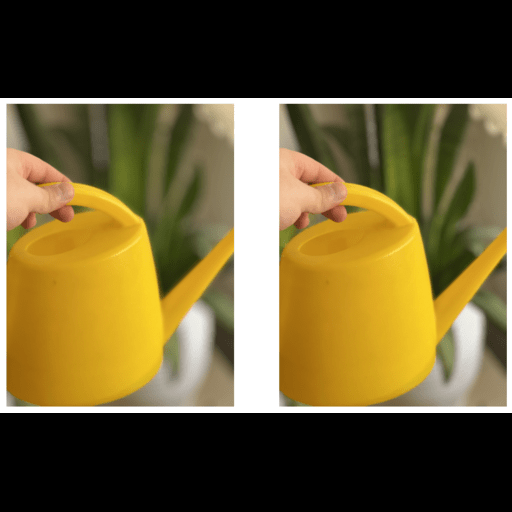
BlurSim

A perceptual loss for comparing blurred images.

GitHub
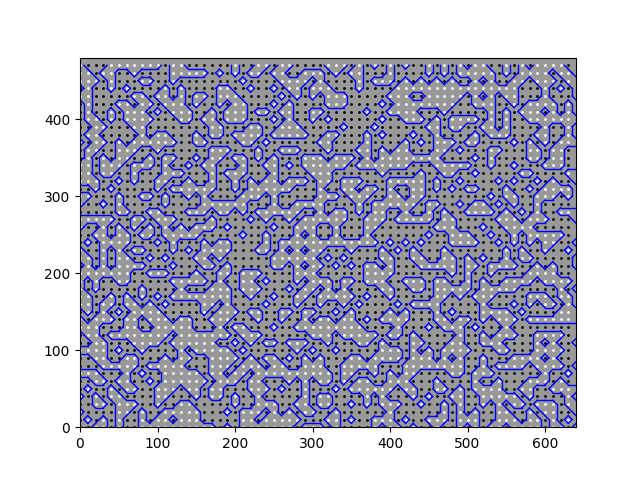
Marching squares

2D terrain generation with noise generators.

GitHub
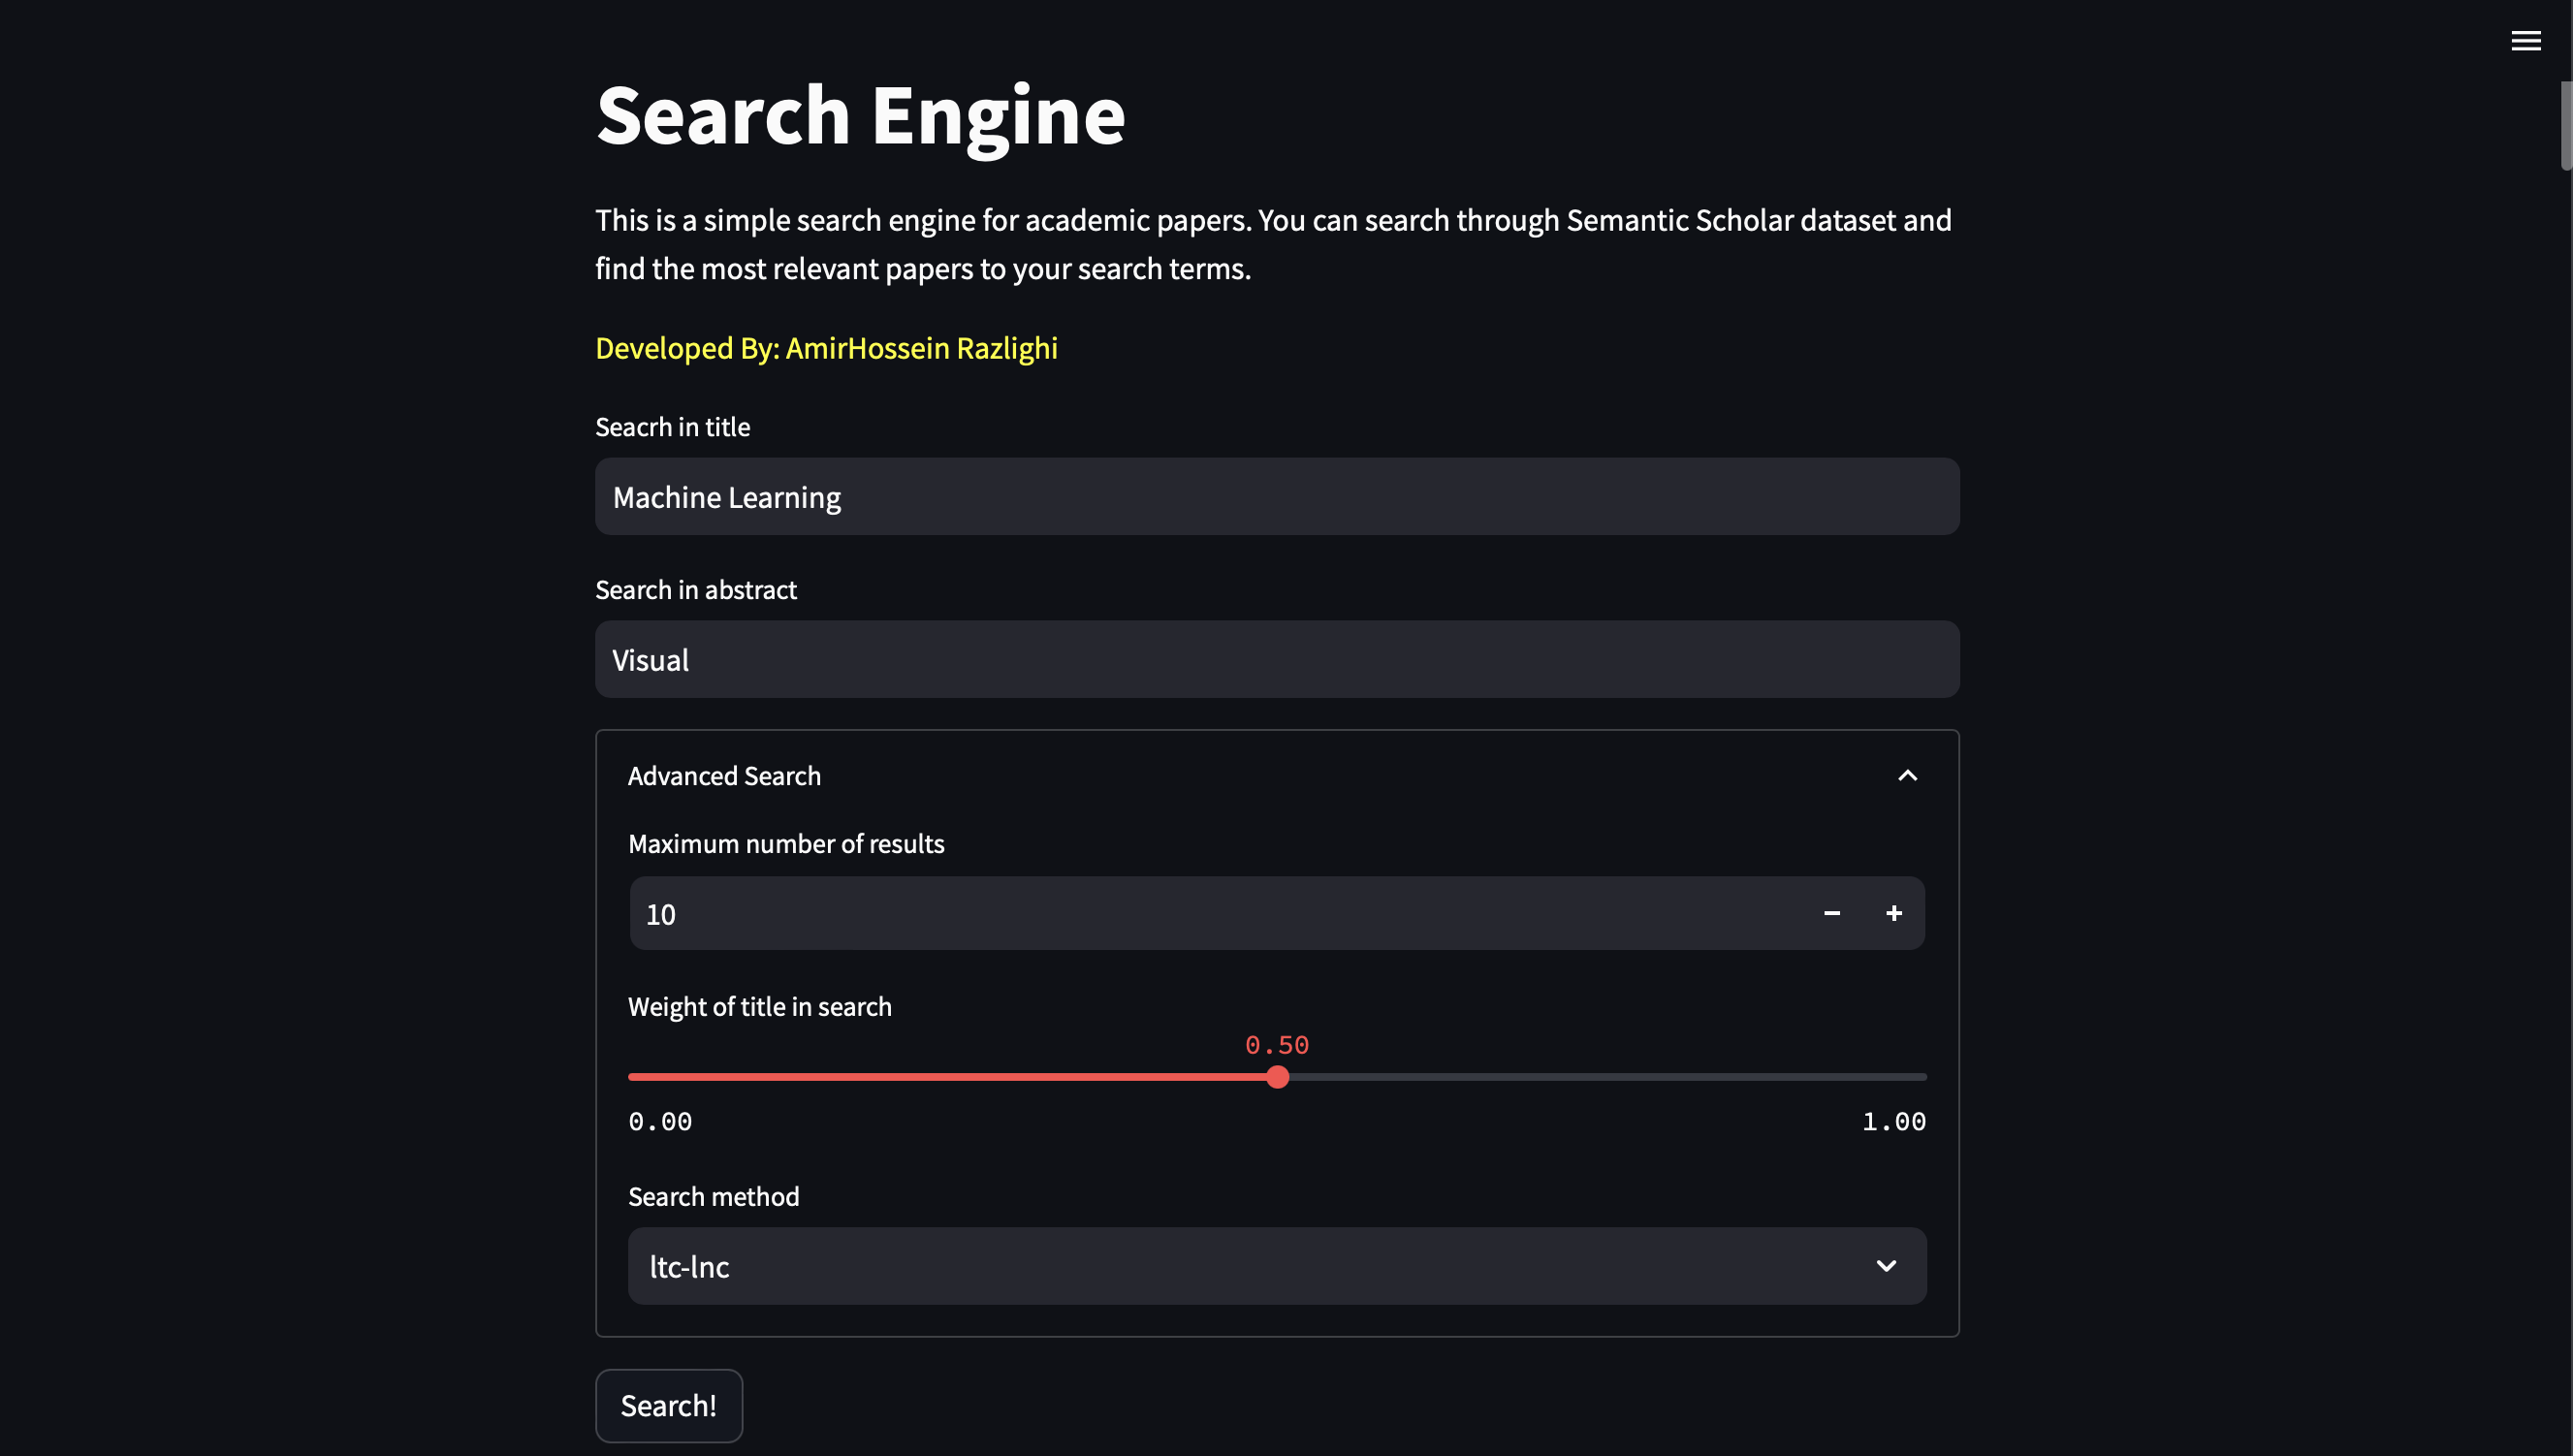
Semantic Scholar search

TF-IDF index, ML ranking and a Streamlit frontend.

GitHub
CMinus compiler

Scanner, parser and semantic analysis, compiling to Python.

GitHub

Teaching and service

Teaching assistant at Sharif University of Technology, Oct 2021 – Jul 2025.

Courses (13)
  • Advanced 3D Computer Vision (grad.): lectures on NeRF and Gaussian Splatting. Prof. Shohreh Kasaei
  • Modern Information Retrieval: head of project. Dr. Mahdieh Soleymani
  • Machine Learning: head TA for projects, managing a team of 10. Dr. Fatemeh Seyed Salehi
  • Digital Image Processing (grad.), Fundamentals of Computer Vision, Scientific and Technical Presentation. Prof. Shohreh Kasaei
  • Artificial Intelligence (two terms): project design. Dr. M. H. Rohban
  • Convex Optimization, Database Design, Linear Algebra, Probability and Statistics, Advanced Programming in Java

Service: Vice President of the Students' Scientific Chapter (SSC) · Head of the Technical Beta Team, Winter Seminar Series · Founder, Byte Publication · RTI Program, Oxford · 3D Vision Reading Group, University of Toronto.

Contact

Email is the best way to reach me. I am glad to talk about video generation, 3D vision or collaborations. Outside research I play video games and read science fiction (Steam, Goodreads).